Voice transcriptions and speech recognition
2019-01-07 — 2026-11-04
In Which Whisper, Parakeet, and Qwen3-Asr Are Employed to Render Audio as Text, Transcriptions Are Aligned via Montreal Forced Aligner, and Dictation Is Facilitated by Serenade and Talon Whilst Music Is Kept at Bay.
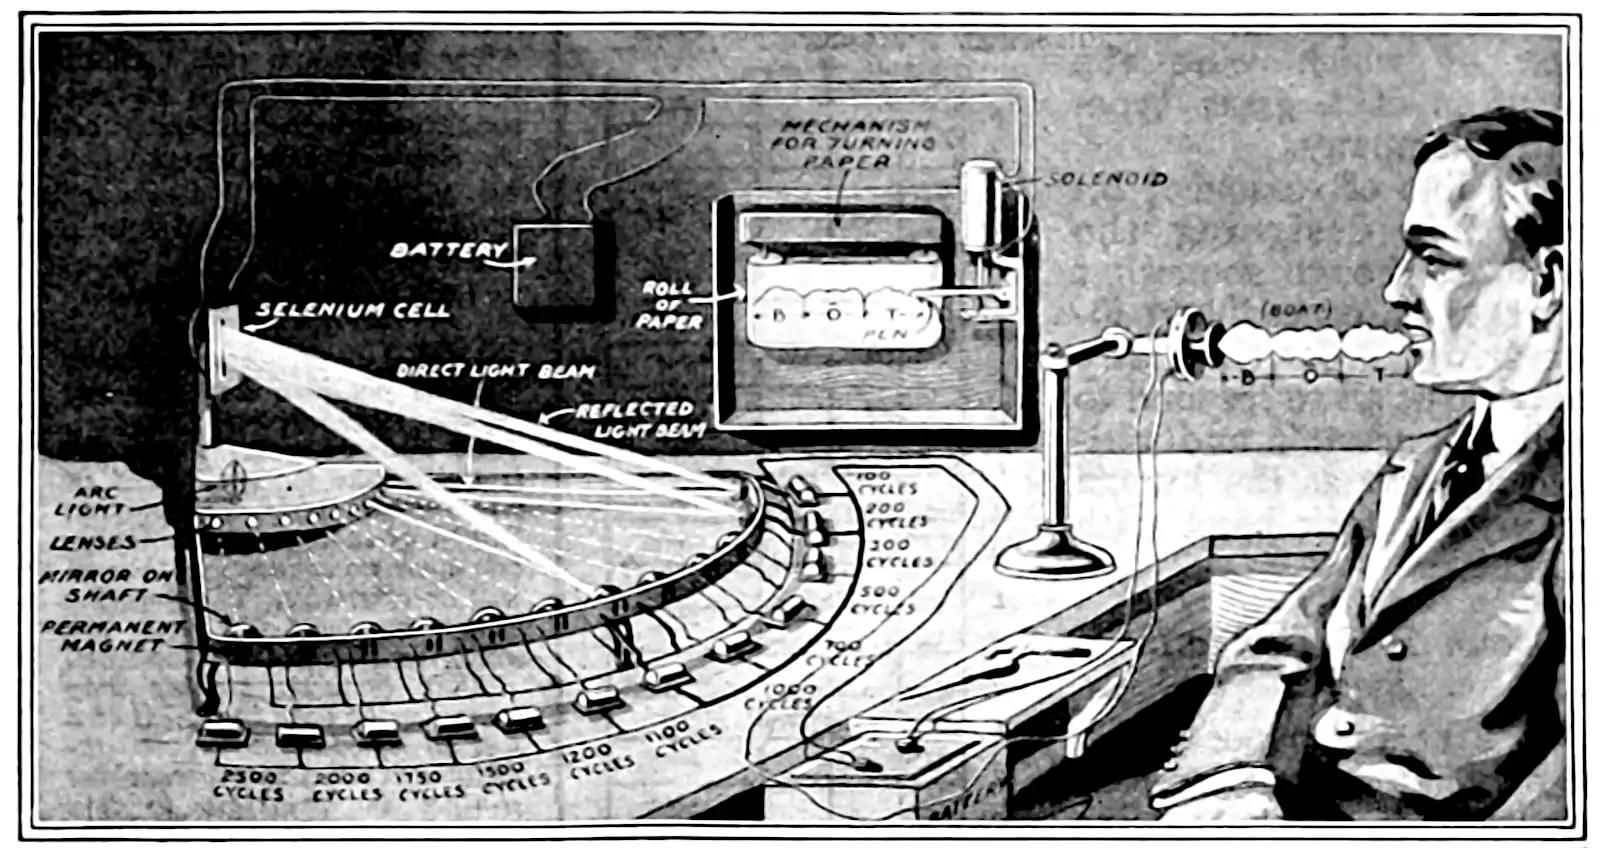
The converse to generating speech from text is generating text from speech. We might do this in real time, to control something or to subtitle, or in batch mode, to turn an audio recording into text. Or we might use a hybrid of both, which ends up being what I typically want in practice when I am attempting to take dictation.
1 Transcribing recordings
What use is a recording if all that delicious speech is not turned into text?
1.1 Whisper
Whisper (Radford et al. 2022) is the epochal speech transcription model that OpenAI released:
Requires a GPU but otherwise free. Has now been integrated into lotsa things.
- openai/whisper: Robust Speech Recognition via Large-Scale Weak Supervision
- whisper/model-card.md at main · openai/whisper
- Whisper - a Hugging Face Space by openai
- HuggingFace Whisper docs
- openai/whisper-large-v3
On Apple Silicon, mlx-whisper is a preferable native route. WhisperX runs CPU-only on macOS, because the CTranslate2 backend has no Metal support. whisper.cpp offers experimental word timing via -ml 1.
1.2 Fast local models
NVIDIA’s Parakeet-TDT is smaller, faster, and hipper than Whisper and benches slightly more accurate. On a Mac, parakeet-mlx runs mlx-community/parakeet-tdt-0.6b-v3. Speed claims, all secondhand:
| Tool | Claimed speed | Source |
|---|---|---|
parakeet-mlx, TDT v3 |
100× real time on an M5 Max | vendor blog |
parakeet-mlx |
~60× (11 min of audio in 14 s) | Reddit anecdote |
mlx-whisper large-v3 |
12–18× on an M5 Max | same vendor blog |
mlx-whisper turbo |
20–30× on an M5 Max | same vendor blog |
mlx-qwen3-asr 0.6B |
RTF 0.08 (12×) on an M4 Pro | its author; one commenter saw 37 GB memory use |
Hours of audio need but minutes of compute either way. Word-timestamp mode in mlx-whisper costs extra.
Parakeet’s timestamps are quantized to an 80 ms grid. The (sub word) token must be merged manually. Default chunking is 120 s windows with 15 s overlap. Alibaba’s Qwen3-ASR comes as ungated open weights at 0.6B and 1.7B parameters. FA-Bench ran the 1.7B weights locally, and they came out ahead of Whisper and Parakeet on word error rate (WER): the number of words substituted, deleted or inserted, as a percentage of the words in a hand-made reference transcript. Qwen3-ASR scored 2.0% on TIMIT and 10.2% on Buckeye, against 2.4% and 11.0% for Parakeet and 2.9% and 13.7% for Whisper large-v3.
If it is more important that the transcript be correct than complete, we can run two unrelated ASR models and drop the passages where they disagree.
1.3 Alignment
i.e. timestamping words, so that we can identify when in a recording a thing was said. e.g. for subtitles, for cutting audio, for building a corpus.
Although some transcription models emit timestamps, they can be deficient. For one thing, most ASR models tidy up speech: they drop “um”, stutters and false starts. That is nice for reading and sounding clever, but bad for mapping text back onto audio since the mapping from text to sound is not bijective, i.e. the ums are smushed into adjacent words.
For another, they are often not super tight. Whisper, for example, is accurate at transcription but it tends to output crappy timestamps which mean it is not good enough to cut or index audio; timestamps run approximately 150ms early (Chu et al. 2026); we need to force alignment for search and indexing.
CrisperWhisper and other related models are trained for verbatim transcription, keeping the fillers, and emitting timestamps on a fine (10 ms) grid. CrisperWhisper’s licence seems suspect (other); we should see how constrained it is.
An alternative pipeline is a two-stage process: transcribe with whatever gives the best text, then hand text and audio to a forced aligner, whose job is to precisely locate the word boundaries in time.
Montreal Forced Aligner (MFA) is a well-regarded open tool. It claims (Chu et al. 2026) to place word boundaries with 20 ms average deviation from hand labels (35 ms if the recording is noisy), at least on US English. It also emits phone timings (i.e. the timings of “individual constituents of speech”). It needs a pronunciation dictionary (English comes in US, UK, Indian, Nigerian and non-native flavours) and installs from conda-forge or Docker. With low-quality inputs, it can be tuned using mfa adapt over the corpus.
CTC aligners such as MMS-FA (bundled in torchaudio.pipelines) or WhisperX’s are less precise but need only a pip install and no dictionary, which typically suffices for coarse applications like subtitles.
1.4 Diarization
Diarization labels not just the words said but who said them, separating out multiple speakers.
The workhorse tool is pyannote.audio and attendant speaker-diarization-community-1 model. It does better if we tell it how many speakers there are. It sends usage telemetry by default; setting PYANNOTE_METRICS_ENABLED=0 stops it. speakrs reimplements the same pipeline in Rust and claims to run about 20× faster.
Diarization degrades when people talk over each other, and on short interjections (“mm”, “yeah”); Half a second of audio is too little for current speaker-recognition models to tell voices apart reliably (Zhao et al. 2025). If misattribution is costly, it is safer to discard overlaps and short turns.
Denoising the audio first does not seem to help (Khan et al. 2025).
1.5 Audio LLMs
Dedicated transcribers are increasingly convergent with general multimodal models. Several of the strongest open transcribers are small LLMs with an audio encoder spliced onto the front: Canary-Qwen-2.5B feeds NVIDIA’s speech encoder into Qwen3-1.7B, and Qwen3-ASR is built on Alibaba’s Qwen3-Omni multimodal model. Meanwhile, general multimodal models such as Qwen3-Omni, Mistral’s Voxtral and NVIDIA’s Audex (Kong et al. 2026) treat transcription as one task among many, maintaining competitive error rates against classics Whisper and Parakeet (Kong et al. 2026).
Pro: Generalist models can conduct more sophisticated analysis of the text, answering questions about it. Con: The general models are usually \(\sim 10 times\) bigger in parameters. Con: They are generally not trained to produce good timestamps.
1.6 Descript
descript aims to integrate editing with transcription, and in particular seems to let us edit audio by editing the transcription, using voice fake technology.
1.7 Misc other
- Vibe is a free, open-source desktop app (macOS, Windows, Linux) for transcribing audio and video files with local Whisper models.
- producthunt transcription options Weaponized social media deep fake here we come. USD 15/month for 10hr/month.
- rev transcription is a human-powered service (USD1.25/minute)
- Vatis tech is AI-backed? USD10/hr. Outputs to video subtitles and identifies different speakers.
- Audioburst offers transcription as part of its podcast service. The price is a mystery.
- The all-manual option: Type it yourself.
- wreally transcribe has built its own in-browser speech recognizer as well as a manual transcription UI. More augmented-manual than automatic. $20/year.
2 Phonetic transcription
It has been a long time since I took Phil Rose’s extravagantly weird undergraduate phonetics class, and I have forgotten much. A cheating tool:
I cannot easily see how to automate phonetic transcription from scratch, but surely that is around somewhere? Some voice transcription software may well use phonetics as an intermediate representation or even as the final output.
If we already have a word transcript, forced alignment gets us most of the way: MFA emits a timed phone list, read off a pronunciation dictionary, with phone-boundary errors of 12–14 ms on clean US English, and presumably worse on anything else. Those are reconstructed from the idealized dictionary pronunciation, so it is a canonical transcription with timings rather than a real phonetic one. Aligners do not seem to emit syllables, although we could deduce them from phones. Tools like PyPI’s syllabify assume US pronunciations, which is suspect for other languages. Or maybe it is fine? In connected speech, syllable boundaries are smeared by coarticulation anyway.
3 Dictation
Speaking as a real-time textual input method.
macOS and Windows both have built-in dictation. So does VS Code Speech, which is good because the macOS one clashes with VS Code’s input method somehow.
Third-party dictation apps have converged on a common pattern: hold a hotkey, speak, release, and the text appears at the cursor, often tidied up by an LLM on the way. Under the hood they mostly run the same fast local models, Parakeet or Whisper, so the audio need not leave the machine. Wispr Flow popularised the pattern, but it is closed-source, paid, and transcribes in the cloud. Adam Jones compared 21 alternatives and picked two open-source ones: Handy (MIT; macOS, Windows and Linux) and, for macOS only, FluidVoice (GPL-3), which shows the transcript live.
4 Coding by voice
I was researching this because I temporarily disabled a hand. For the moment, the easiest option was to use Serenade for Python programming, OS speech recognition for prose typing, and to leave my other activities aside for now. If my arms were to be disabled for a longer period, I would have probably accepted the learning curve of using Talon, which seems to solve more problems, at the cost of greater commitment.
These days I would probably switch to a hybrid code generation workflow where I generate code by plain language, which removes a lot of the specialist speech recognition problems.
See Speaking in code: how to program by voice (Nowogrodzki 2018)—
Coding by voice command requires two kinds of software: a speech-recognition engine and a platform for voice coding. Dragon from Nuance, a speech-recognition software developer in Burlington, Massachusetts, is an advanced engine and is widely used for programming by voice, with Windows and Mac versions available. Windows also has its own built-in speech recognition system. On the platform side, VoiceCode by Ben Meyer and Talon by Ryan Hileman … are popular.
Two other platforms for voice programming are Caster and Aenea, the latter of which runs on Linux. Both are free and open source, and enable voice-programming functionality in Dragonfly, which is an open-source Python framework that links actions with voice commands detected by a speech-recognition engine.
See also: Programming by Voice May Be the Next Frontier in Software Development.
One point of friction I didn’t anticipate is that most of these tools will, for various reasons, do their best to switch off any music playing whenever I use them. For someone like me who can’t focus for three minutes straight without banging electro in the background, this isn’t ideal. My current workaround is to play music on a different device so I can sneak beats past my unnecessarily diligent speech recognition tools trying to stifle background noise or whatever it is they’re doing. This means I’m wearing two headsets, which looks funny, but to be honest, it isn’t the worst fashion sacrifice I’ve been forced to make in the course of this particular injury.
Contrariwise, if I were to try to use speech control in an open-plan office, coworking space, or the family living room, it would be excruciatingly irritating for anyone else who could hear me. My current workaround, when I’m annoying some innocent bystander with my narration, is to accuse them of being ableist if they complain.
4.1 Doing without a mouse
Try stylus or eye tracking systems, in addition to Talon, below.
4.2 GitHub Copilot voice
Might be interesting.
4.3 Serenade
Simple, low-lift, intuitive voice recognition for coding. Includes deep integration for various languages and various code editors, including Visual Studio Code and those JetBrains ones. Free. Simple to use.
Supported languages: Python, JavaScript, HTML, Java, C / C++, TypeScript, CSS, Markdown, Dart, Bash, Sass, C#, Go, Ruby, Rust.
The experience is good for plain code; I used this for about 2 months when I had a broken arm. Editor integration isn’t awesome when using Jupyter, in line with the general rule that Jupyter makes everything more flaky and complicated.
4.4 Talon
tl;dr:
Powerful hands-free input
- Voice Control — talk to your computer
- Noise Control — click with a back-beat
- Eye Tracking — mouse where you look
- Python Scripts — customise everything
Full length:
🤳Talon aims to bring programming, realtime video gaming, command line, and full desktop computer proficiency to people who have limited or no use of their hands, and vastly improve productivity and wow-factor of anyone who can use a computer.
[…] - Powerful voice control - Talon comes with a free speech recognition engine, and it is also compatible with Dragon with no additional setup. - Multiple algorithms for eye tracking mouse control (depends on a single Tobii 4C, Tobii 5 or equivalent eye tracker) - Noise recognition system (pop and hiss). Many more noises coming soon. - Scriptable with Python 3 (via embedded CPython, no need to install or configure Python on your host system). - Talon is very modular and adaptable - you can use eye tracking without speech recognition, or vice versa.
Worked example: Coding with voice dictation using Talon Voice.
4.5 Cursorless
An advanced coding extension for VS Code.
Cursorless is a spoken language for structural code editing, enabling developers to code by voice at speeds not possible with a keyboard. Cursorless decorates every token on the screen and defines a spoken language for rapid, high-level semantic manipulation of structured text.
It seems to be based on Talon.
4.6 Dragonfly
Dragonfly is a speech recognition framework for Python that makes it convenient to create custom commands to use with speech recognition software. It was written to make it very easy for Python macros, scripts, and applications to interface with speech recognition engines. Its design allows speech commands and grammar objects to be treated as first-class Python objects. Dragonfly can be used for general programming by voice. It is flexible enough to allow programming in any language, not just Python. It can also be used for speech-enabling applications, automating computer activities and dictating prose.
Dragonfly contains its own powerful framework for defining and executing actions. It includes actions for text input and key-stroke simulation. This framework is cross-platform, working on Windows, macOS and Linux (X11 only). See the actions sub-package documentation for more information, including code examples.
This project is a fork of the original t4ngo/dragonfly project.
Dragonfly currently supports the following speech recognition engines:
- Dragon, a product of Nuance. All versions up to 15 (the latest) should be supported. Home, Professional Individual and previous similar editions of Dragon are supported. Other editions may work too
- Windows Speech Recognition (WSR), included with Microsoft Windows Vista, Windows 7+, and freely available for Windows XP
- Kaldi (under development)
- CMU Pocket Sphinx (with caveats)
4.6.1 Mathematics
4.7 VoiceCode
Your voice is the most efficient way to communicate. VoiceCode is a concise spoken language that controls your computer in real-time. When writing anything from emails to kernel code, to switching applications or navigating Photoshop — VoiceCode does the job faster and easier.
VoiceCode is different from other voice-command solutions in that commands can be chained and nested in any combination, allowing complex actions to be performed by a single spoken phrase.
By taking advantage of your brain’s natural aptitude for language you can control your computer more efficiently and naturally.